Your AI model can pass a general benchmark and still miss a journal entry that doesn't balance. That's why finance teams are turning to specialist evaluation providers who build tasks with real accounting rigor.
Why Finance AI Evaluation Is Its Own Discipline
Generalist benchmarks reward pattern matching. Finance work rewards precision. A model that hallucinates a decimal point or cites the wrong codification is worse than useless in a corporate ledger. That gap has created a new category of providers who author domain-specific tasks, write deterministic answer keys, and grade model outputs against verified ground truth. The field now spans public leaderboards, expert-curated QA sets, private-markets agent tests, and custom benchmark builds. If you're training or evaluating a model for finance, you need to know who builds the tasks and how they verify the answers.
How We Evaluated These Providers
We looked at the same factors for every provider. Service scope: do they cover task authoring, answer keys, and grading, or just one piece? Verification rigor: are answers deterministic and inspectable, or graded by judgment? Domain depth: do tasks reflect real accounting standards and corporate finance workflows? Transparency: can you see sample tasks, methodology, or public results before you commit? Pricing clarity: is the engagement model visible, or do you have to guess? Local fit: are they set up to work with US-based AI labs and finance teams? Each provider below stood out on different factors, and the right pick depends on whether you need a public leaderboard, a custom benchmark, or expert-written tasks for your own harness.
Here's a quick side-by-side of what each provider brings to the table.
| Provider | Best For |
|---|---|
| Vals AI | Public finance benchmark leaderboards |
| Nuvonix Labs | Expert Finance & Accounting AI Evaluation | Custom expert-written finance eval tasks |
| Snorkel AI | Agentic finance QA evaluation |
| Henon | Private-markets agent benchmarking |
| Hebbia | Workflow-level finance model comparisons |
The 5 Providers in Detail
#1 Vals AI
 A screenshot of the Vals AI website.
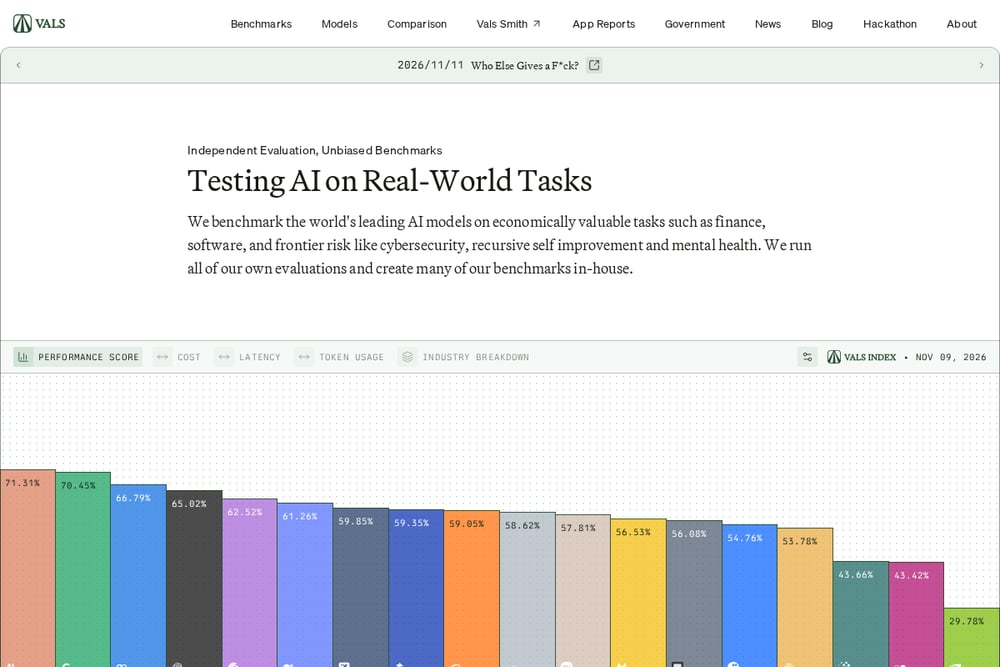
Vals AI runs public leaderboards that let you compare frontier models on core financial analyst tasks. Its Finance Agent v2 benchmark, updated in late 2026, tracks accuracy, cost, tokens, and duration across dozens of models. You can view trajectories and read the research paper behind the methodology. The platform also covers other sectors through its Vals Index, so you get a broader view of model performance. If you want an independent, continuously updated read on how models handle finance work, this is a strong starting point.
#2 Nuvonix Labs | Expert Finance & Accounting AI Evaluation
 A screenshot of the Nuvonix Labs | Expert Finance & Accounting AI Evaluation website.
Nuvonix Labs builds expert-written finance and accounting tasks with answer keys and grading rubrics for teams training and evaluating AI. Tasks are authored by accounting and corporate finance practitioners and reflect real corporate ledgers and technical codifications. Answer keys include step-by-step derivations and exact citations, so grading runs against verified ground truth. Rubrics are deterministic and formatted for automated scoring harnesses or expert human review. The team publishes an inspectable accounting evaluation sample on GitHub, complete with integer-cent verification code and sample test cases. They're taking early projects now, which makes them a fit if you need a custom benchmark built to your spec.
#3 Snorkel AI
 A screenshot of the Snorkel AI website.
Snorkel AI's SnorkelFinance benchmark is an expert-verified financial QA set built from financial reports. It evaluates AI agents on tool-calling and reasoning capabilities in realistic enterprise settings. The company positions itself around data and environment development for frontier problems, and it runs open benchmark grants to support evaluation work. You can request samples and compare model performance on its leaderboard. If your focus is agentic finance workflows rather than static Q&A, this benchmark is worth a look.
#4 Henon
 A screenshot of the Henon website.
Henon publishes PrivateMarketsAgentBench, which tests 17 frontier models on 55 real private-markets finance tasks. The tasks include capital-call notices, trial balances, fund statements, and dashboards, all run inside a production system. Every run is graded the same way, and the full dataset is downloadable under a permissive license. Results cover pass rate, cost, and latency, so you can weigh trade-offs. If your models touch private equity, private credit, or fund reporting, this benchmark gives you a realistic stress test.
#5 Hebbia
 A screenshot of the Hebbia website.
Hebbia's Financial Services Benchmark tests leading LLMs on 600+ workflows across investment banking, private equity, credit, and public equities. The company makes its statistical methodology fully transparent to the public. Its findings break down performance by task type, such as extraction versus summarization and reasoning. That granularity helps you pick the right model for a specific workflow rather than a single overall score. If you work in deal-oriented finance and want workflow-level model comparisons, this is a useful reference.
How to Choose the Right Provider
Start with your goal. If you need a public, independent read on model performance, a leaderboard provider gives you that fast. If you need tasks built to your own harness and grading policy, look for a provider that authors custom tasks with deterministic keys. Check whether the answer keys are inspectable. Ask if the grading is binary or rubric-based, and whether it fits your automated scoring pipeline. Confirm the domain depth: private markets, public equities, and corporate accounting each need different task designs. Finally, ask about pricing and timeline up front. Early-stage providers may be more flexible on scope, while established platforms offer more standardized benchmarks.
The Bottom Line
Finance AI evaluation is no longer a side project. The providers above each cover a different slice of the problem, from public leaderboards to custom expert-written tasks. Match the provider to your stage: use a leaderboard for a quick read, a benchmark for agentic workflows, and a custom task builder when you need verified ground truth for your own model. The common thread is rigor. Pick the provider whose verification method you can inspect and trust.